SpaceXAI released Grok 4.7 on Monday as its most capable model for coding and knowledge work, at the same $2/$6 per-million-token price as Grok 4.6, live in Cursor, Grok Build, and the Grok API — competitive on price-performance while still trailing Fable on several coding and office benches.
SpaceXAI, Elon Musk’s xAI lab, introduced Grok 4.7 on Monday, September 21, 2026, calling it the company’s most capable model for coding and knowledge work. In the official post, the lab said the model works longer on difficult tasks, checks its own work more carefully, and ships with its best-calibrated safeguards to date — at the same price and speed as Grok 4.6.
Larger base, longer RL, same sticker
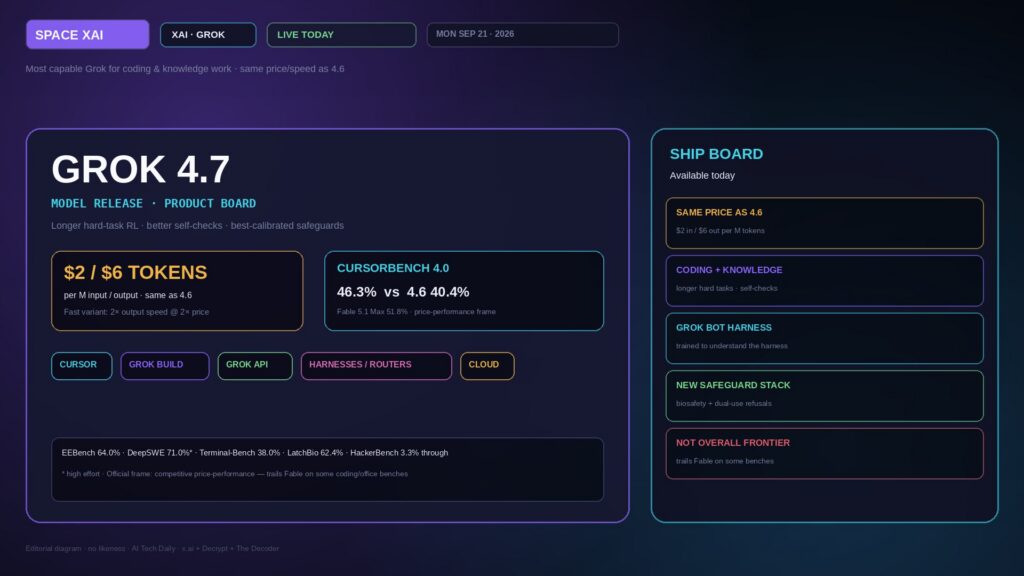
Grok 4.7 uses a larger base than 4.6, trained with a longer reinforcement-learning run on harder multi-hour tasks, with better long-context handling and native understanding of the Grok Bot harness, the company said. Pricing starts at $2 per million input tokens and $6 per million output tokens; a fast variant doubles output speed at double the price. Availability is immediate in Cursor, Grok Build, the Grok API, third-party coding harnesses, and model routers and cloud platforms.
Decrypt reported the launch followed multiple delays since late July and attributed a 2.1 trillion-parameter claim to coverage of the release; that figure does not appear in the SpaceXAI news post.
Benchmarks: price-performance, not a clean lead
On CursorBench 4.0, SpaceXAI posted Grok 4.7 at 46.3% versus Grok 4.6 at 40.4%, GPT-5.6 Sol Max at 41.7%, and Fable 5.1 Max at 51.8%. DeepSWE v1.1 (high effort) rose to 71.0% from 4.6’s 65.2%. EEBench hit 64.0%, ahead of Fable at 56.4% and Sol at 39.4%. AA Briefcase v1.1 scored 1,657 versus 4.6’s 1,546 and Fable’s 1,678. Terminal-Bench 4.0 jumped to 38.0% from 20.3%, still behind Fable’s 57.9%. Harvey Legal landed at 19.6%; HealthBench Professional at 56.7%. Decrypt separately cited GDPval at 1,695 versus Fable at 1,735. The company framed the model as frontier on price-performance for longer coding tasks — not as an overall frontier leader.
Safeguards and cyber red-team
SpaceXAI said Grok 4.7 uses a new safeguard stack, topping LatchBio’s biosafety benchmark at 62.4% and allowing only 3.3% of risky dual-use prompts through on HackerBench v0.3, with invite-only cyber red-team access for select defense partners. The Decoder likewise stressed bargain pricing against a still-visible gap to Claude and GPT-class peers on several independent reads.
Sources
- https://x.ai/news/grok-4-7
- https://decrypt.co/378824/xai-launches-grok-4-7
- https://the-decoder.com/xai-launches-grok-4-7-at-bargain-prices-but-benchmarks-reveal-a-wide-gap-to-claude-and-gpt-6/